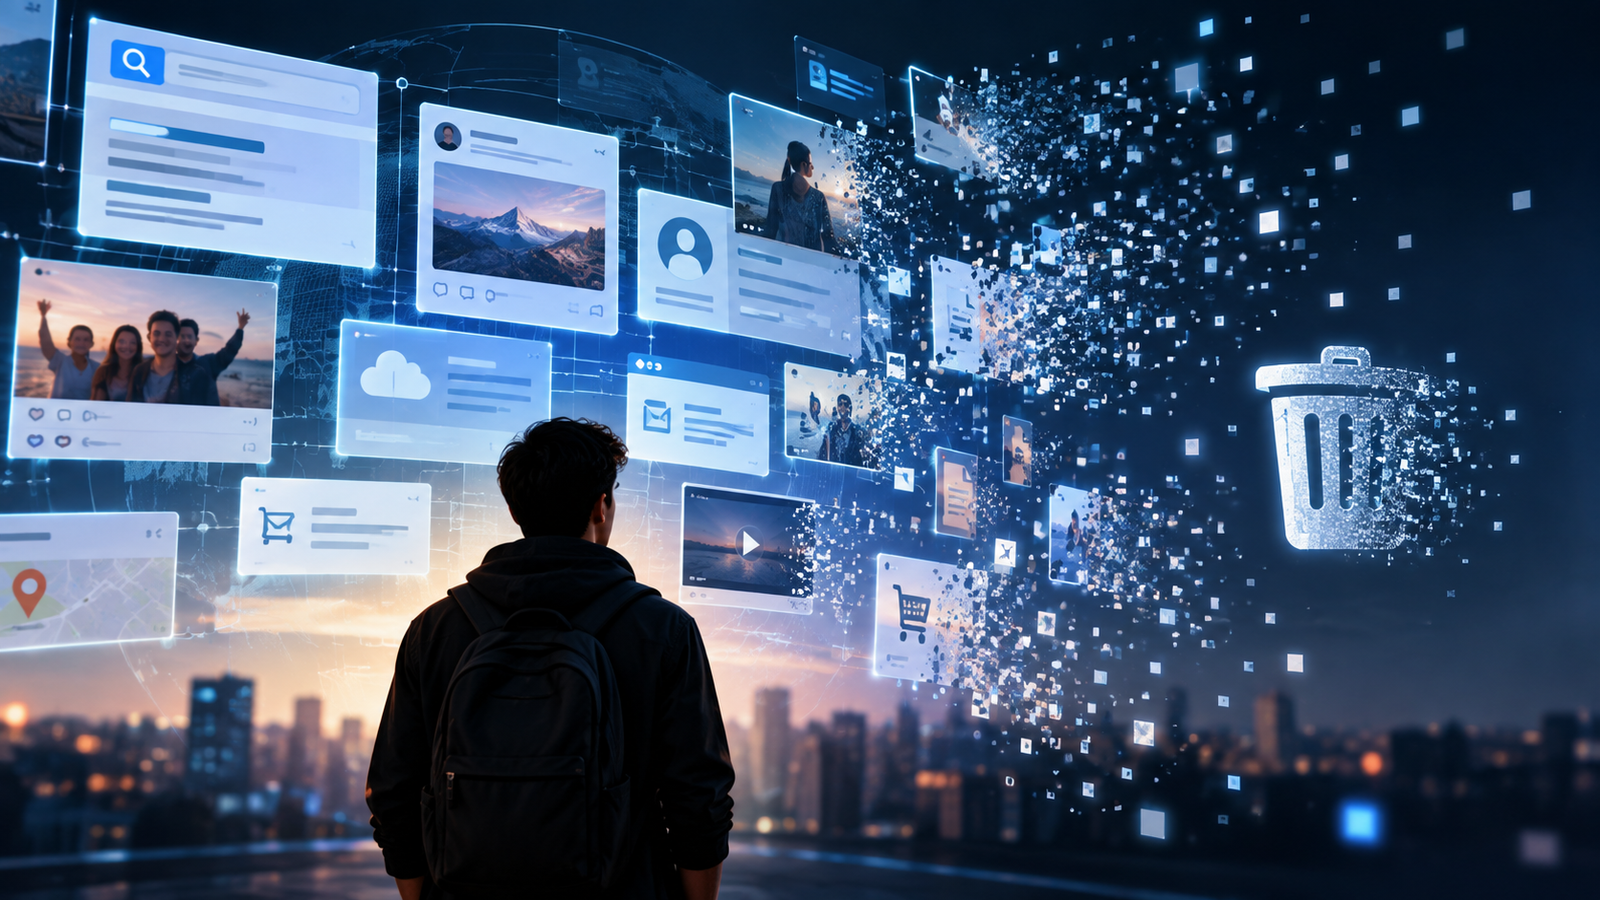
The internet is often described as a place that never forgets. A photo uploaded years ago can resurface, an old social media post can remain searchable, and information shared on one website can be copied to many others without the original creator even knowing where it went. We have built an enormous digital memory that records conversations, purchases, locations, photographs, searches, preferences, and countless other pieces of information. But this raises an interesting question: what if the internet could forget you? What if information about a person did not have to remain available forever, and technology could actually make certain digital traces disappear when they were no longer needed?
For most of the history of the internet, remembering information was considered a feature. Websites stored user accounts so people could return to them. Search engines indexed pages so information could be found quickly. Cloud services created backups so files would not be lost. Social media platforms preserved posts, photographs, messages, and interactions. Businesses stored customer information because it helped them understand their users and provide services. In many ways, the internet became a giant memory system. The problem is that human memory and digital memory work very differently. People naturally forget things, but computers can store information for years with almost no effort.
Imagine posting an embarrassing photograph when you are eighteen years old and deleting it a few months later. You might believe the photograph is gone. But someone could have downloaded it, taken a screenshot, shared it in a private group, or uploaded it somewhere else. Search engines may have indexed a copy, websites may have cached information, and backup systems may still contain older versions. The original deletion therefore does not necessarily mean that every copy has disappeared. This is one of the biggest challenges behind the idea of a digital world that can truly forget.
This problem has led to an important concept known as the right to erasure, often discussed as the “right to be forgotten.” The basic idea is that, under certain circumstances and subject to important exceptions, individuals may have rights concerning the deletion or removal of personal information. However, this does not mean that anyone can simply ask the internet to erase anything they dislike. There can be competing interests, including freedom of expression, public interest, legal obligations, journalism, research, and the need to maintain certain records. In practice, forgetting information is therefore much more complicated than pressing a delete button.
There is also an important difference between deleting information and making it difficult to find. Suppose someone searches for your name and finds an old article containing personal information about you. A search engine might remove that result from searches for your name while the original article continues to exist on the website that published it. The information has become harder to discover through that particular search, but it has not necessarily been erased from the internet. This distinction shows why digital forgetting is not simply a technical problem. It involves technology, law, businesses, and society all at the same time.
The technical side becomes even more complicated when we consider how modern websites store information. A single piece of data may exist in several places at once. A social media application might have the original post in its main database, copies in backups, records in analytics systems, images stored in separate storage systems, and information reproduced in recommendation or search systems. A company may also have logs created when the data was accessed. Deleting one record does not automatically mean that every related record disappears.
Backups create another interesting problem. Companies create backups because they need to recover information if a system fails, becomes corrupted, or is attacked. If a user deletes an account today, should every backup containing information about that account also be immediately destroyed? Doing that could make reliable disaster recovery extremely difficult. Instead, systems may have different retention periods and processes for handling deleted information. This means that “delete” can sometimes mean “remove from active systems while older backup copies expire later,” rather than “destroy every digital copy instantly.”
The problem becomes even more interesting when artificial intelligence enters the picture. AI systems can process enormous amounts of information and use data during training, evaluation, retrieval, or other parts of an AI workflow. If information about a person has already been incorporated into a complex model, deleting the original webpage does not necessarily mean that the model has automatically forgotten everything related to it. This raises a difficult technical question: if a person asks a system to forget something, what exactly should forgetting mean?
One possibility is to remove the original data from the systems that directly store it. Another is to prevent the information from being retrieved or displayed. A more complicated approach could involve techniques that allow models or databases to reduce the influence of particular information without rebuilding an entire system from scratch. Researchers have been exploring areas such as machine unlearning, which investigates how machine-learning systems can be modified to remove the influence of selected training data. The goal is not simply to press delete on a file but to investigate whether a system can meaningfully “unlearn” information.
This becomes particularly important because information can travel far beyond its original source. Consider a simple example. Someone writes a review on a website. Another website quotes it. A social media user shares a screenshot. A search engine indexes the page. A news article references the discussion. Another service collects publicly available information. An automated system processes the content. At that point, the original website is only one part of a much larger information chain. Asking the original website to delete the review does not automatically reverse everything that happened afterward.
There is another technology that makes digital forgetting particularly difficult: blockchain. Traditional databases can generally be changed by the organisation controlling them. Blockchains are designed around distributed records and strong resistance to alteration. Once information is added to certain blockchain systems, removing or changing that information can conflict with the fundamental design of the technology. This creates an interesting tension between permanent digital records and privacy principles that may require information to be deleted under particular circumstances.
The future of privacy may therefore depend less on building systems that remember everything and more on building systems that understand how long information should live. Imagine creating a social media post with an expiration date. Instead of simply pressing delete later, you could specify that the information should exist for a particular period. After that period, the system could automatically remove it from active databases and associated services according to predefined rules. Temporary digital identities could work in a similar way, allowing people to interact with online services without creating permanent profiles that follow them for decades.
This idea could also change the way websites are designed. Today, many services encourage users to create permanent accounts because long-term data is valuable to businesses. A future privacy-focused system might instead collect the minimum information necessary, keep it only for as long as necessary, and automatically remove information that no longer serves a useful purpose. This approach would change data from something that companies automatically keep into something that has a defined digital lifetime.
The concept of digital forgetting could even change how people think about their online identity. Today, a person's digital identity can become a collection of everything they have ever posted, searched, purchased, liked, uploaded, or interacted with. But people change. A teenager becomes an adult. A student becomes a professional. Someone's interests change, opinions evolve, friendships end, and mistakes become lessons. If technology permanently preserves every stage of a person's life, the digital version of that person may become much less flexible than the real person.
At the same time, complete digital forgetting may not always be desirable. Historical records can be valuable. Public information can be important for accountability. Scientific research depends on reliable records. Businesses need certain information for legal and financial reasons. Journalists may need to preserve evidence. A system that automatically erased everything after a certain period could create its own problems. The challenge is therefore not simply deciding whether information should be remembered or forgotten. The real challenge is deciding what should be remembered, for how long, by whom, and under what conditions it should disappear.
This also changes the responsibility of technology companies. If a company collects personal information, should it be responsible only for storing that information securely, or should it also be responsible for determining when the information should no longer exist? Should users be able to see what information a company has about them? Should they be able to request deletion through a simple interface? Should businesses be required to explain which copies can be deleted immediately and which may remain temporarily because of backups or legal requirements?
There is also a question of whether people themselves should become more conscious of the lifespan of digital information. The internet makes sharing incredibly easy. A photograph can be uploaded in seconds, but removing every copy of that photograph may be impossible. A message written impulsively can be screenshotted before it is deleted. A comment made years ago can become searchable long after the person has changed. The ability to publish instantly has therefore created a responsibility to understand that digital information can have a much longer life than we expect.
Perhaps the future internet will not be defined by how much information it can remember, but by how intelligently it can forget. Instead of treating every piece of data as something that should be stored indefinitely, future systems could give information a lifecycle. Some data could exist for seconds, some for days, some for years, and some permanently when there is a legitimate reason to preserve it. Users could have greater visibility and control over this lifecycle, while businesses could design their systems around data minimisation and responsible retention.
The idea of a forgetting internet does not mean creating an internet with no memory. It means creating an internet with a better understanding of memory. Human beings are not defined by everything they have ever done, and perhaps our digital identities should not be either. As technology becomes more powerful and artificial intelligence becomes increasingly capable of processing enormous amounts of information, the ability to decide what should disappear may become just as important as the ability to store it.
The internet was built to make information available. The next generation of technology may need to answer a different question: when should information no longer be available? The answer will not be simple, and there will probably never be a universal delete button for the internet. But building technology that respects the lifespan of personal information could bring us closer to a digital world where people have more control over their past. In a world that has become exceptionally good at remembering, learning how to forget may become one of the most important technologies of all.